A narrower job for AI: returning a value rather than composing an answer
Cloudflare’s October 19 announcement introduces Clairic on Workers AI as a preview for extracting, computing, estimating and forecasting values. It plans to release open weights later. This is not evidence that a self-hostable release is available today.
The useful change in emphasis is the shape of the task. An application may need a particular amount or date, not a paragraph describing one. Returning the requested kind of value can simplify the connection between a model and ordinary software. That convenience does not settle whether the value has the intended meaning.
Our technical reading begins by separating three questions: what form can the answer take, what input supports it, and what conclusion does a person draw from it? Those questions remain different even when all three are represented by one tidy number. This article explains the distinction; it does not offer a performance ranking.
Source notes: 1. Original editorial examples and interpretations are identified separately.
Read, calculate and predict are different claims about evidence
Cloudflare distinguishes reading explicit input, calculating from facts, estimating an unknown and forecasting a sequence. These operations have different evidential roles, not just different names for a numeric output.
Consider this original, invented parts record: four packages each weigh 0.75 kilograms, and the packaging adds 0.20 kilograms. Reading the quantity identifies four. Computing the specified total gives 4 × 0.75 + 0.20 = 3.20 kilograms. The multiplication follows stated assumptions; we have not asked Clairic to perform it.
Now ask whether the delivery will arrive tomorrow. The weight record does not determine that outcome. A numeric estimate would address an unknown event, rather than recover another fact hidden in the arithmetic. More decimal places cannot bridge that difference. Any useful prediction would need relevant evidence about the delivery, not merely a well-described weight field.
This is why our suggested interpretation attaches a short explanation of the result’s role: read from a source, derived under stated rules or predicted beyond what is known. That explanation can be more useful than displaying every output with the same visual certainty.
Source notes: 3. Original editorial examples and interpretations are identified separately.
The type can be right while the interpretation is wrong
The model reference describes typed field specifications, text spans identifying positions in the input, scalar confidence information and null results. The concept guide separately warns that constraints govern the possible form of an answer, not its correctness.
Return to the invented weight calculation. An output of 3.20 would be a valid number whether the receiving application expected kilograms or grams. Its digits alone would not reveal the disagreement. Field names, units and the intended quantity therefore belong to the question, not just to the decoration around the answer.
The same applies to a constrained range. In an original illustrative counterexample, suppose a forecast is allowed to return only zero through ten arriving parcels, but the actual count is fourteen. A result inside the permitted range can satisfy the requested format and still miss reality. The chosen bounds did not make the world obey them.
Source positions can help a reviewer inspect nearby words, but the reviewer still needs to establish what those words refer to. Locating a number and understanding its role are separate achievements. We have not tested how reliably this preview makes that distinction on difficult inputs.
Source notes: 2, 3. Original editorial examples and interpretations are identified separately.
A missing answer changes how a result should be counted
The concept guide says a scalar null can mean the information is absent or that the model failed to identify it. It also says estimates and forecasts can return predictions despite limited evidence. Missingness and an uncertain prediction are therefore not interchangeable outputs.
Here is a separate original evaluation exercise, not a Clairic benchmark. Imagine one hundred questions, with twenty unanswered and seventy-two correct among the eighty answered. Counting only answered questions gives 72/80 = 90% correctness. Counting correct answers across every question gives 72/100 = 72%, alongside a 20% unanswered share.
Neither fraction needs to be fraudulent, but they answer different questions. The first describes correctness conditional on an answer being returned; the second describes how many questions received a correct answer overall. A buyer could misunderstand the system if a comparison presents one fraction while silently implying the other.
Our proposed assessment would retain the unanswered cases and examine why they were unanswered. A useful refusal to guess and a missed explicit fact have different implications. This exercise illustrates the accounting; we have collected no such cases from Clairic and do not estimate its actual error or abstention rate.
Source notes: 3. Original editorial examples and interpretations are identified separately.
An interval describes a prediction, not an appointment with reality
Cloudflare’s guide describes the interval between the tenth and ninetieth percentiles as the middle 80% of a predicted distribution. It warns that actual coverage can vary between tasks and datasets. The announcement likewise cautions that calibration can deteriorate on unfamiliar data.
For another independent teaching example, suppose a forecaster labels one hundred intervals as 80% intervals, and seventy-six later contain the corresponding observed outcomes. Their measured coverage in that invented set is 76/100 = 76%. The label and the measurement are not identical, and one small set cannot establish a universal property.
Coverage alone is also not the entire usefulness question. An interval so broad that it rarely misses may provide little help with a decision that needs a narrower distinction. Conversely, a very narrow interval can look informative while failing to include the outcome often enough. Report what the interval is intended to describe and how its behavior was assessed.
Our recommendation is to preserve that context when an estimate is passed to another application. Do not turn a predicted range into a deadline, a guaranteed minimum or a verified measurement simply because the next screen has room for only one number.
Source notes: 1, 3. Original editorial examples and interpretations are identified separately.
Our assessment: make the task measurable before calling the answer trustworthy
Our assessment is that structured output is valuable infrastructure, but an evaluation still needs a clear target. Identify the intended quantity, the evidence available at the time, the treatment of unanswered cases and the conditions under which an output will be used. These definitions should remain visible when comparing results, not disappear behind a single score.
The original examples show three distinct failure modes: a correctly formatted value with the wrong meaning, an attractive accuracy fraction with a hidden denominator and an uncertainty label without demonstrated coverage. None establishes that Clairic suffers those failures in practice. They identify what a meaningful independent assessment would need to investigate.
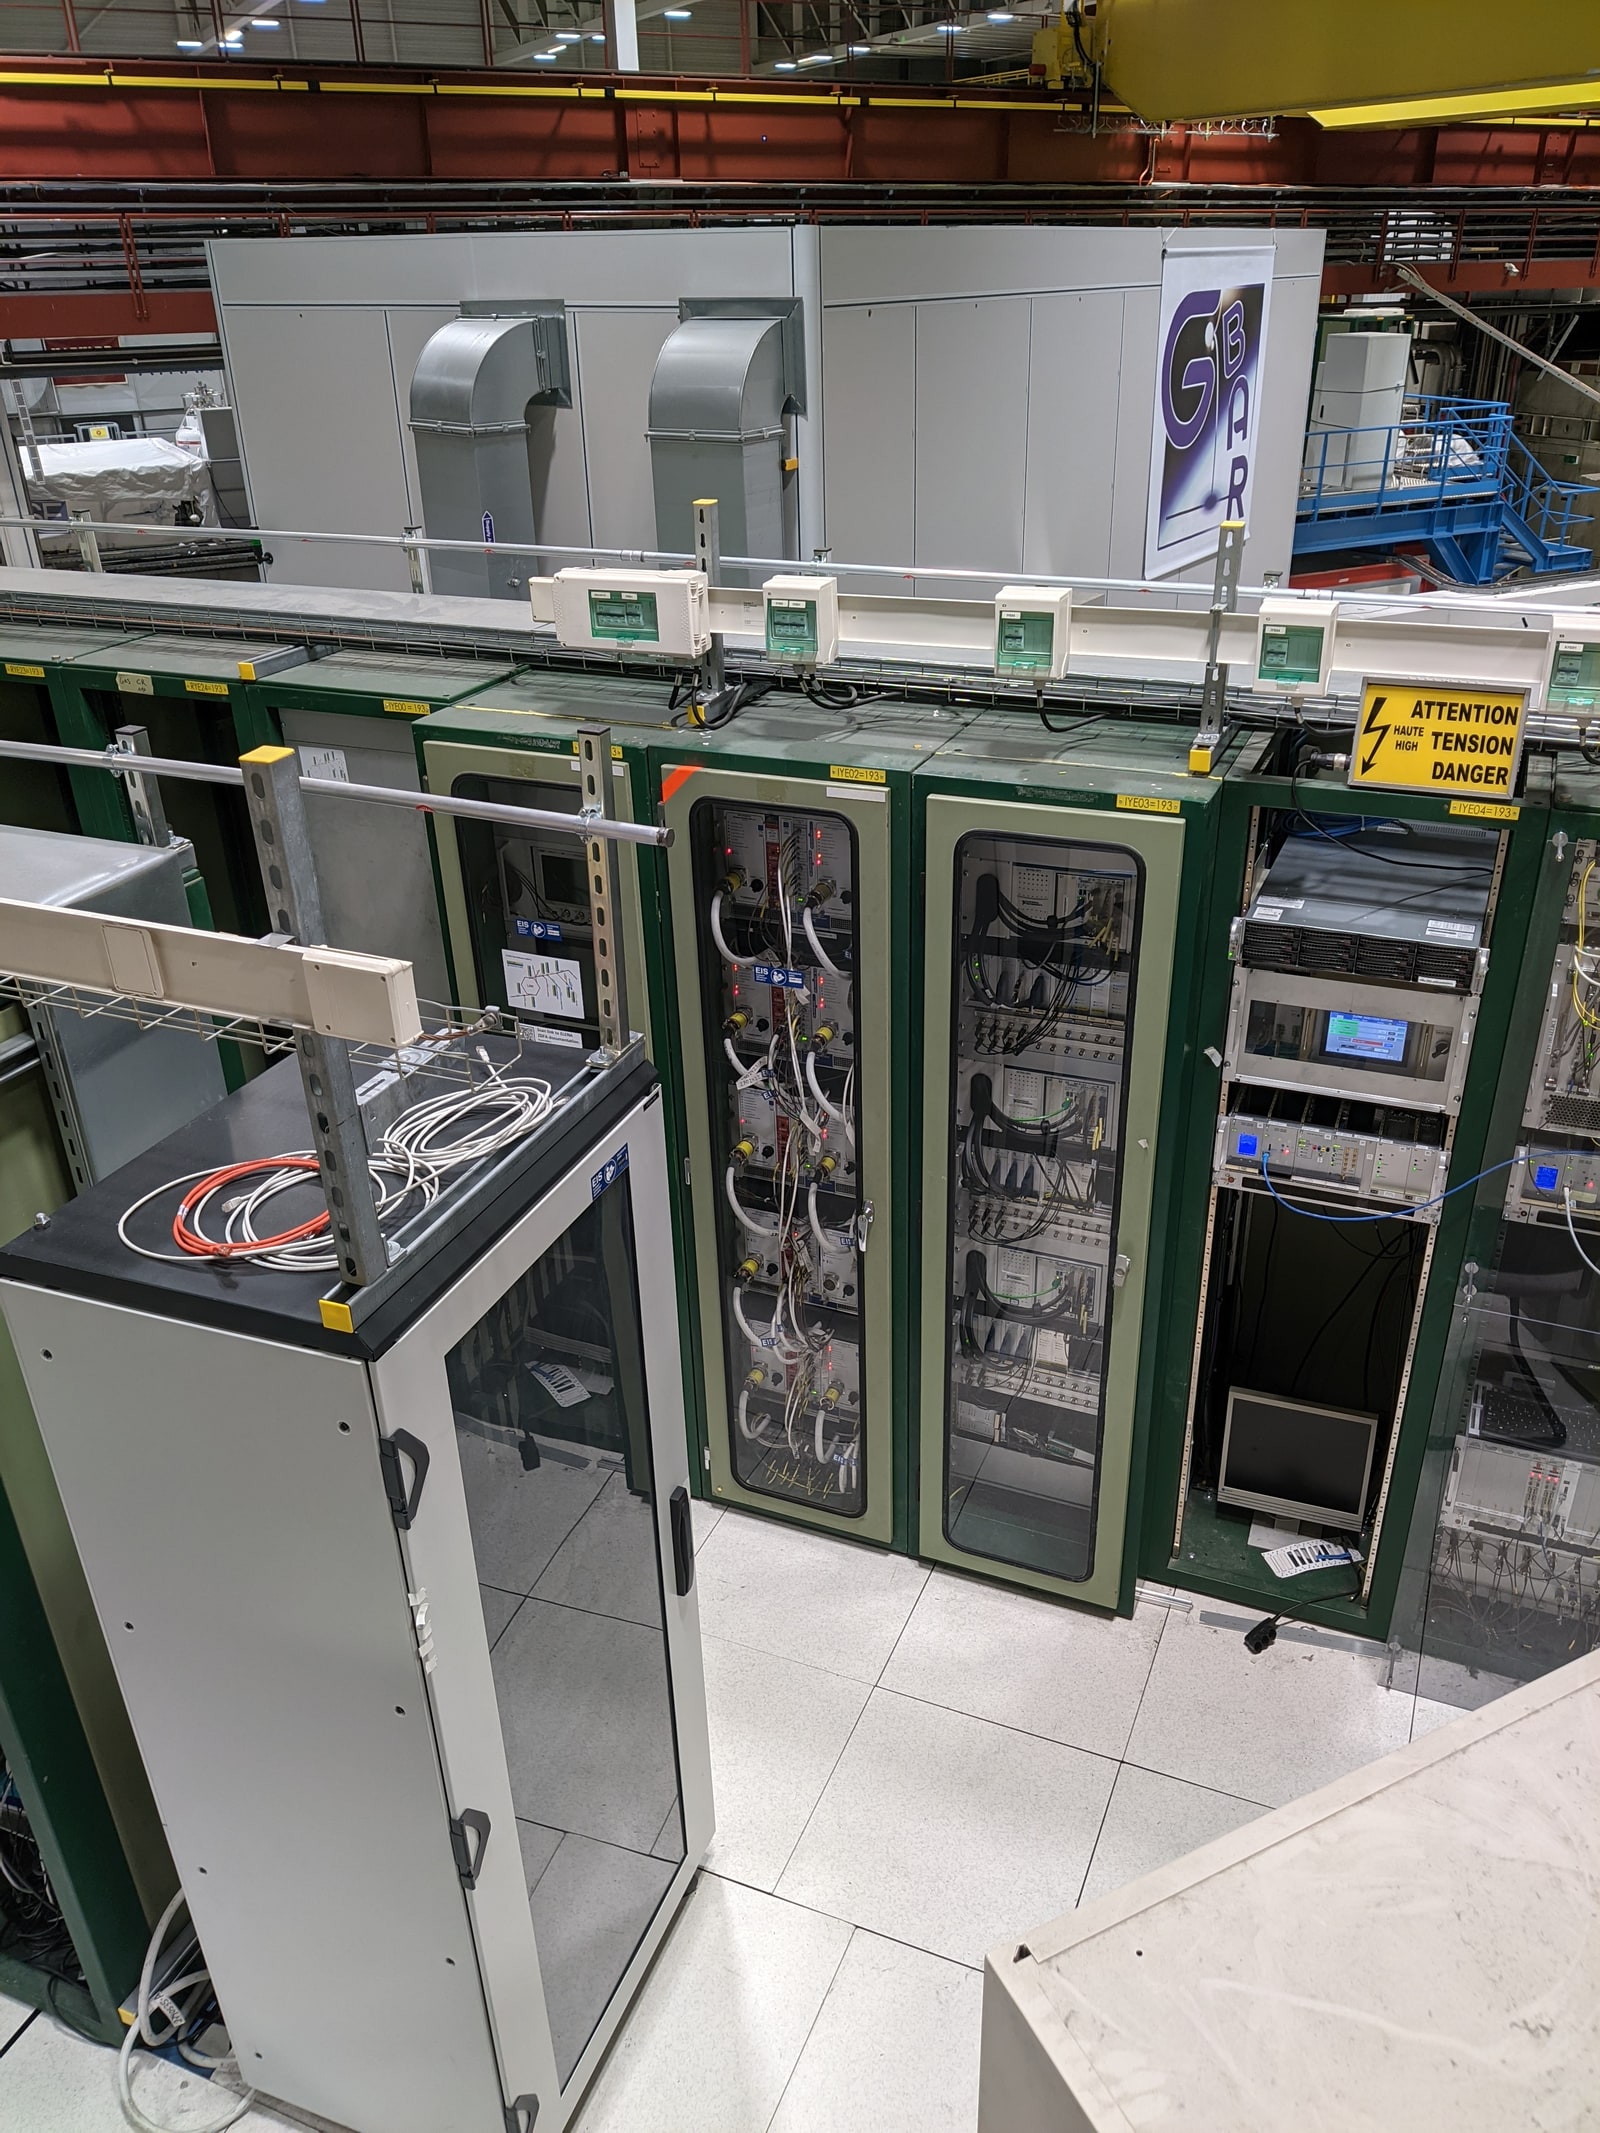
We read the product documentation rather than running the preview, and do not reproduce the vendor’s speed or cost comparison as our own result. The archive photograph shows CERN server racks photographed in 2024, not Cloudflare hardware or an installation running Clairic. The next useful evidence is task-specific performance with its limits retained—not a more confident adjective attached to the same formatted answer.
Source notes: 1, 2, 3. Original editorial examples and interpretations are identified separately.
Sources & Methods
Prepared October 20, 2026 from the complete October 19 Cloudflare announcement, the complete Clairic model reference and the complete extraction-model concept guide. These are three provider sources, not independent validations. Parts arithmetic, unanswered-case accounting and interval-coverage examples are original invented illustrations. No model requests, account changes, software installation, speed benchmark, calibration study or interview was performed. Photographer, capture date, file metadata, public profile and full reuse deed were read separately. Publisher context: LUMACTA uses Cloudflare Pages to host this website; that is a separate service and not a test of Workers AI or Clairic.
- Cloudflare: October 19 announcement — Primary provider announcement; complete main body read
- Cloudflare: Clairic reference — Primary provider documentation; complete model information, usage, parameters and terms read
- Cloudflare: extraction concepts — Primary provider explanation; complete capabilities, uncertainty, constraints and limitations read